Modern dedicated servers are built on faster hardware than ever: NVMe SSDs with massive parallel queue depths, multi-core CPUs, and network interfaces running at 10 Gbps, 25 Gbps, or 100 Gbps. Yet raw hardware speed only tells half the story. If the software layer between an application and the kernel is inefficient, a fast Linux dedicated server can still leave performance on the table.
This is the problem io_uring was built to solve.
io_uring is a modern Linux asynchronous I/O interface that lets applications submit and complete I/O operations through shared ring buffers instead of issuing a constant stream of individual system calls. For database servers, web applications, game servers, and storage platforms running on high-performance dedicated servers, that difference in I/O design can directly affect throughput, latency, and CPU efficiency.
This guide breaks down what io_uring is, how it works, where it fits into dedicated server infrastructure, and just as importantly, when it isn't the right tool for the job.
What Is io_uring?
io_uring is a Linux kernel interface designed to reduce the overhead of submitting and completing I/O requests. Traditional Linux I/O relies heavily on system calls: every read, write, or network operation typically means a round trip between user space and kernel space. For workloads generating thousands of small or concurrent operations, common on busy database or storage dedicated servers, that constant context-switching adds up in wasted CPU cycles.
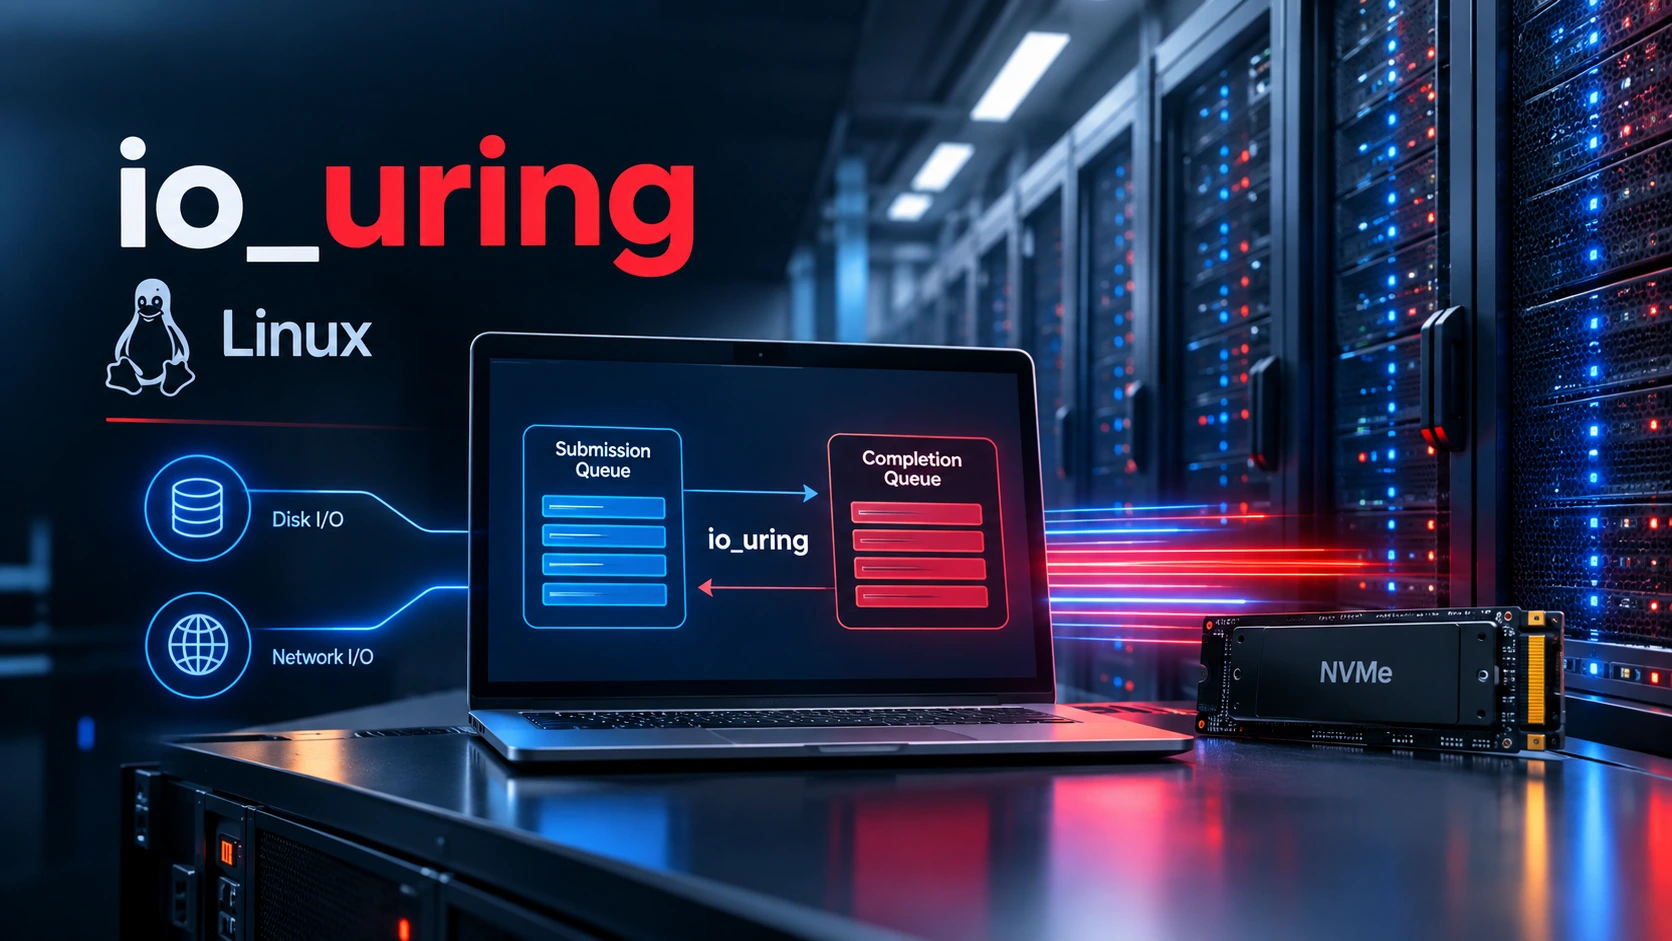
io_uring replaces much of that overhead with two shared ring buffers:
-
Submission Queue (SQ): where an application places I/O requests, known as Submission Queue Entries (SQEs), for the kernel to process.
-
Completion Queue (CQ): where the kernel writes results back as Completion Queue Entries (CQEs), once each operation finishes.
Because submission and completion are decoupled, an application can queue up many operations before checking on any of them — a pattern well suited to servers handling high concurrency. The Linux kernel documentation also shows io_uring extending beyond simple file I/O into subsystems such as FUSE and userspace block-device (ublk) infrastructure, underscoring that it has become a general-purpose async I/O foundation rather than a single-use API.
How io_uring Works: The Submission and Completion Model
At a high level, an io_uring workflow follows six steps:
-
The application creates an io_uring instance.
-
I/O requests are prepared as submission queue entries.
-
The requests are submitted to the kernel, often several at once (batching).
-
Linux processes the operations asynchronously.
-
Finished operations land in the completion queue.
-
The application reads the completion entries and acts on the results.
The key architectural shift is that submission no longer blocks on completion. A database engine, for instance, can queue multiple reads and writes against NVMe storage and keep working while the kernel and the drive process them in parallel — rather than treating every operation as an isolated, synchronous event.
Why io_uring Matters on Modern Dedicated Server Hardware
Server hardware has moved faster than many I/O models were originally designed for. NVMe SSDs can sustain enormous numbers of outstanding operations at very low latency. CPUs now ship with dozens of cores. Network adapters increasingly run at 25 Gbps and above.
When hardware capability increases, software coordination overhead becomes the bottleneck. An I/O interface built around older assumptions may not fully exploit what today's storage and networking hardware can deliver. io_uring is designed around high concurrency and efficient request handling, helping applications keep fast NVMe dedicated servers and high-throughput network interfaces busy instead of stalled on system-call overhead.
That said, io_uring is not an automatic performance upgrade. The real-world gain depends on workload type, application architecture, kernel version, storage hardware, network hardware, and how well the software implements async I/O.
io_uring and Disk I/O on Dedicated Servers
Storage performance is one of the clearest places io_uring proves useful. Conventional file I/O — opening, reading, writing, and waiting on each operation — introduces coordination overhead that scales poorly with concurrency. io_uring's asynchronous model lets an application submit many file operations at once and process completions as they arrive.
This pattern is particularly relevant for:
-
High-IOPS databases (PostgreSQL, MySQL)
-
File and storage servers
-
Backup systems and log processing
-
Media and content processing pipelines
-
Virtualization platforms
-
High-concurrency web applications
An application handling thousands of files, for example, can submit a batch of reads without waiting on each one individually, letting the underlying NVMe dedicated server storage work on multiple requests in parallel while the application processes whatever completes first. The performance gain isn't just "faster disk speed"; it's a function of queue depth, request size, filesystem behavior, and application design working together.
io_uring and NVMe SSD Performance
NVMe storage was purpose-built around a queue-based, highly parallel architecture — which makes it an ideal match for io_uring's submission-and-completion model. Modern NVMe drives can support a large number of outstanding commands with very low latency, but if the application layer is inefficient at issuing and tracking those requests, some of that hardware capability simply goes unused.
On a dedicated server built around NVMe storage, this is especially relevant for:
-
PostgreSQL and MySQL workloads with heavy concurrent I/O
-
Large-scale search and indexing systems
-
High-traffic application servers
-
Object and file storage platforms
-
Virtual machine disk I/O
-
High-concurrency APIs
It's worth noting that io_uring changes how efficiently an application talks to storage; it doesn't remove other potential bottlenecks like CPU scheduling, memory bandwidth, filesystem overhead, or database locking.
io_uring for Network I/O
io_uring also extends to Linux networking, supporting socket operations such as accepting connections, receiving data, and sending data within the same asynchronous framework used for storage. For servers managing thousands of simultaneous connections, this reduces the amount of application code dedicated to repeatedly submitting and waiting on individual network operations.
A more recent addition, io_uring zero-copy receive (io_uring zcrx), allows supported configurations to deliver incoming packet data directly into userspace memory, eliminating a kernel-to-user copy step on the receive path. This is an advanced, hardware-dependent capability rather than a universal networking upgrade; it requires compatible NICs and specific receive-queue configuration.
Why Fewer Memory Copies Matter
Every time data moves between kernel space and user space, it consumes CPU cycles and memory bandwidth. For a high-throughput network application, repeated copying of packet payloads before they reach the application adds measurable overhead. Zero-copy techniques, including io_uring's zero-copy receive path, aim to cut that unnecessary movement, which becomes especially valuable when:
-
Network throughput is very high
-
CPU overhead is a limiting factor
-
Large volumes of data are transferred continuously
-
Application-level latency is critical
According to the Linux kernel documentation, io_uring zero-copy receive is distinct from a full kernel-bypass approach like DPDK; the kernel's TCP stack still processes packet headers, so it's a targeted optimization rather than a bypass of the networking stack.
io_uring vs. Traditional Linux I/O
The architectural difference is easiest to see side by side:
-
Traditional synchronous I/O: Application → system call → kernel → I/O operation → application waits or continues per the API contract
-
Asynchronous io_uring model: Application → prepare requests → submission queue → kernel processes operations → completion queue → application handles results
The io_uring model shines when an application needs to manage many independent operations concurrently. That doesn't make conventional I/O obsolete; it remains mature, well-supported, simpler to implement, and fast enough for a large share of workloads. io_uring becomes the more compelling choice once I/O volume, concurrency, latency sensitivity, or CPU overhead becomes a measurable constraint.
io_uring vs. epoll
io_uring and epoll solve related but different problems. epoll is an event-notification mechanism; it tells an application when a file descriptor is ready for an operation like reading or writing. io_uring is a broader asynchronous I/O interface that lets an application submit operations directly and receive completion notifications for them.
For many network-only applications, epoll remains an excellent, proven choice. io_uring becomes more attractive when an application wants a single, unified asynchronous model that spans both storage and network operations. The right choice depends on software architecture and workload, not simply which API is newer.
Key io_uring Features Relevant to High-Performance Servers
-
Asynchronous I/O: operations are submitted without blocking, allowing many requests to stay in flight.
-
Batching: multiple operations can be prepared and submitted together, cutting per-operation coordination cost.
-
Submission and Completion Queues: a structured channel between application and kernel for requests and results.
-
Registered buffers: applications can pre-register memory buffers, reducing repeated memory-management overhead.
-
Fixed file and buffer operations: avoids repeatedly resolving the same resources for certain workloads.
-
Multishot operations: a single submitted request can generate multiple completions, cutting down on repeated setup.
-
Zero-copy techniques: under supported conditions, including io_uring zero-copy receive for networking.
Where io_uring Fits Into Dedicated Server Workloads
Because a dedicated server gives an application full, uncontended access to CPU, memory, storage, and network resources, io_uring's benefits are easier to measure and reproduce compared with shared or heavily virtualized environments. Relevant use cases include:
-
Database servers: High-IOPS NVMe storage paired with efficient asynchronous I/O can benefit workloads with substantial concurrent database activity, provided the database engine's storage subsystem is built to use io_uring.
-
Web and application servers: Applications maintaining thousands of simultaneous connections while reading files, querying databases, and writing logs can manage that concurrency more efficiently with an async I/O model.
-
Game servers: Latency, connection handling, and predictable resource usage matter most here; efficient asynchronous operations support suitable server architectures.
-
Storage servers: Workloads generating large numbers of simultaneous read/write requests benefit directly from io_uring's asynchronous file operation model.
-
Virtualization platforms: Virtual machines generate heavy disk and network activity; efficient I/O handling helps keep storage and networking pipelines from becoming a bottleneck.
-
High-throughput network applications: Large connection volumes or data transfers can benefit from asynchronous networking and, where supported, zero-copy techniques.
-
Content and media processing: Applications handling many large files can overlap storage operations with CPU-based processing rather than waiting on each in turn.
What Actually Determines io_uring Performance
Describing io_uring as simply "faster I/O" oversimplifies things. Real-world performance depends on the whole system working together:
-
CPU: more cores support more concurrent work, but scheduling and application design still matter.
-
RAM: memory bandwidth and capacity affect buffering and caching.
-
Storage type: NVMe, SATA SSD, and HDD each have distinct latency and throughput profiles.
-
Queue depth: how many operations are outstanding at once changes device and application behavior.
-
Filesystem: ext4, XFS, and others behave differently under concurrent I/O.
-
Kernel version: io_uring continues to evolve, and supported operations vary across Linux kernel releases.
-
Application architecture: the biggest single factor; an application must be built or configured to use async I/O effectively.
-
Network hardware: advanced features like zero-copy receive depend on NIC capability and configuration.
How to Check io_uring Availability on a Linux Dedicated Server
Start by checking the kernel version:
uname -r
Then check whether io_uring has been restricted at the kernel level:
sysctl kernel.io_uring_disabled
Per the Linux kernel documentation, a value of 0 allows normal instance creation, while 1 or 2 impose restrictions or disable creation entirely. Keep in mind that availability alone doesn't guarantee usage; the application, runtime, or library still needs to implement io_uring support.
Applications and Libraries That Use io_uring
Most developers won't interact with raw io_uring structures directly. Libraries such as liburing provide a higher-level interface for applications adopting async I/O. The technology also underpins other Linux subsystems; the kernel's ublk (userspace block device) framework, for instance, uses io_uring passthrough commands to bridge the kernel block layer and userspace components. This reflects a broader trend: io_uring is becoming core Linux I/O infrastructure, not a niche storage API.
io_uring Security and Administration Considerations
Performance is only one side of adopting a new I/O interface; security and operational discipline matter just as much on a production Linux dedicated server. The kernel.io_uring_disabled sysctl exists specifically to let administrators reduce kernel attack surface by restricting unprivileged processes from creating new io_uring instances.
Before deploying io_uring in production, evaluate:
-
Linux kernel version and update cadence
-
Application and library compatibility
-
User privilege levels
-
Resource limits
-
Monitoring and observability tooling
-
Security policy alignment
-
Workload-specific, measured performance impact
Does Every Dedicated Server Need io_uring?
No, and that's an important, honest answer. Fast hardware alone doesn't create a need for io_uring. Traditional Linux I/O APIs remain mature, stable, and more than sufficient for a large share of workloads.
io_uring earns its place once profiling shows that I/O submission, completion handling, system-call overhead, or concurrency management is a real, measured bottleneck. A sound evaluation process looks like this:
-
Measure the current workload's I/O behavior.
-
Identify the actual bottleneck; don't assume.
-
Benchmark an io_uring-based implementation.
-
Compare CPU usage, latency, IOPS, throughput, and tail latency.
-
Test under realistic, production-like load.
-
Deploy only if the measured improvement justifies the added complexity.
This prevents optimizing a part of the stack that was never actually the constraint.
Optimizing a Linux Dedicated Server for I/O Performance
io_uring is one lever among several. For storage-heavy workloads, also consider:
-
NVMe SSD storage and appropriate RAID configuration
-
Sufficient RAM for buffering and caching
-
Filesystem selection suited to the workload
-
Database-specific tuning
-
Ongoing monitoring of disk latency and IOPS
-
Minimizing unnecessary background I/O
-
Keeping the kernel and storage drivers current
For network-heavy workloads, also consider:
-
Network interface speed and latency to end users
-
CPU headroom for packet processing
-
RSS and receive-queue configuration
-
TCP tuning
-
Connection concurrency limits
-
NIC driver and firmware currency
-
Application-level batching
-
Zero-copy options where hardware supports them
Hardware selection should always come before micro-optimization; no I/O interface can compensate for storage, memory, CPU, or network capacity that's fundamentally undersized for the workload.
Choosing the Right Dedicated Server for I/O-Intensive Workloads
If your application is storage- or network-bound, running it on dedicated infrastructure gives you direct control over the hardware and kernel configuration that io_uring depends on. When evaluating a provider for I/O-heavy workloads, look at:
-
CPU architecture, core count, and clock speed
-
RAM capacity
-
NVMe SSD performance and storage configuration/RAID
-
Network port speed and latency to your users
-
Data center location and available dedicated server locations
-
DDoS protection
-
Operating system support and root access
-
Monitoring and technical support quality
COLO BIRD offers dedicated server configurations across multiple global locations, including NVMe storage, high-speed networking, GPU servers, and dedicated storage server builds — the kind of hardware foundation that lets an io_uring-based application architecture actually deliver on its performance potential. Review the available high-performance dedicated servers and hardware options, or check the dedicated server FAQ for common configuration questions before selecting a build for an I/O-intensive workload.
Frequently Asked Questions About io_uring
Q: What is io_uring in Linux?
io_uring is a Linux asynchronous I/O interface that uses submission and completion queues to manage I/O operations between applications and the kernel more efficiently than traditional system calls.
Q: Is io_uring faster than traditional Linux I/O?
It can be, for suitable workloads, particularly applications performing many concurrent operations that can take advantage of batching and asynchronous processing. The actual gain depends on the application, kernel version, hardware, and workload type.
Q: Does io_uring improve NVMe SSD performance?
io_uring helps applications use NVMe storage more efficiently through asynchronous, concurrent I/O. It doesn't change the physical performance ceiling of the drive itself.
Q: Can io_uring improve network performance?
Yes, for suitable applications. Linux also provides an io_uring zero-copy receive feature that can eliminate a kernel-to-user memory copy on supported network hardware and configurations.
Q: Is io_uring better than epoll?
They aren't direct substitutes. epoll handles event notification for file descriptors; io_uring provides a broader asynchronous I/O interface spanning storage and network operations. The right choice depends on application architecture.
Q: Do all Linux applications support io_uring?
No. Applications, libraries, runtimes, or frameworks need explicit implementation to use io_uring — its presence in the kernel doesn't automatically convert existing software to use it.
Q: Is io_uring available on dedicated servers?
Yes, as a Linux kernel interface, it's available on dedicated servers running a compatible kernel. Administrators should verify the kernel version and check whether io_uring has been restricted via kernel.io_uring_disabled.
Q: Does io_uring require NVMe storage?
No. io_uring supports multiple I/O types; NVMe is simply one environment where its efficiency gains are especially visible.
Q: Can io_uring reduce CPU usage?
For some workloads, yes; reducing system-call and coordination overhead can lower CPU cost. This should always be measured directly, since the effect depends heavily on application behavior.
Q: What is io_uring zero-copy networking?
io_uring zero-copy receive (zcrx) is a Linux networking feature that can deliver incoming packet data directly into userspace memory, skipping a kernel-to-user copy step on supported hardware and configurations.
Final Takeaway
io_uring represents a meaningful shift in how Linux handles I/O, replacing a constant stream of individual system calls with a queue-based, asynchronous model built for concurrency. For workloads running on NVMe storage and high-speed networking, that architecture can translate into measurable gains in throughput, latency, and CPU efficiency.
But io_uring isn't a universal switch that makes every application faster. The organizations that get the most out of it are the ones that measure their actual bottleneck, match the I/O model to their application's real behavior, and run it on hardware capable of supporting the workload in the first place. A properly configured Linux dedicated server with adequate CPU, NVMe storage, and network capacity remains the foundation that any async I/O strategy is built on.
 Explore Our Global Dedicated Server Locations
 Your Voice Matters: Share Your Thoughts Below!
 Recent Topics for you